The Second Workflow Is the Real Test
The first deployment solves a problem. The next one reveals what you actually built.
Consider a manufacturer that receives a supplier invoice for more parts than the receiving team has recorded. Someone in accounts payable opens the invoice, finds the purchase order, checks the delivery record, and emails the warehouse. The answer comes back: part of the shipment is still on the truck.
This is a good place to start with AI. Give the system read access to those records. Let it compare quantities, point to the mismatch, and prepare a note for the person who decides what happens next. Keep payment approval with accounts payable.
Suppose that works. The records line up, the reviewer can check the evidence, and the team wants to keep using it.
Then someone asks a reasonable question: can it help handle the supplier dispute, too?
Same invoice. Same order. Same missing parts. It sounds like a small extension.
That is where I would start paying closer attention.
This example is illustrative, not a report of a client deployment.
The neighboring problem
The first workflow asks whether the invoice matches the records. The second asks what the company should say or offer when it does not.
That second question reaches further. The remaining parts might be in transit, rejected at inspection, or delivered to the wrong location. The supplier may have sent a credit that has not reached the ledger. Procurement may have agreed to a partial delivery by email. The warehouse count might simply be late.
The system can find a discrepancy without knowing which of those explanations holds. Drafting a dispute from the discrepancy alone could turn a lagging record into an unnecessary fight with a supplier.
Still, the two workflows have a great deal in common. Both need to find the correct invoice and order. Both need the source behind a quantity. Both need to know whether a record is current and who can see it. Having solved those problems once should make the next workflow easier.
The useful question is how much easier, and why.
What should survive the move
Connecting to a document store is a start. The more valuable work is deciding what a retrieved record means.
Does this invoice belong to the supplier's billing entity or its parent company? Is this purchase order the current revision? Does “received” mean unloaded at the dock or accepted after inspection? If the first workflow depended on somebody quietly answering those questions, the second workflow will depend on that person too.
A stronger first deployment leaves those answers somewhere the next workflow can use them.
The connection returns the document version and the time it was read. The quantity points to a particular line on a particular record. Supplier and order identifiers resolve consistently. Access rules follow the records into the new task. A reviewer can correct a match, and that correction remains available with its reason and scope.
None of this guarantees a good dispute decision. It does mean the team can spend its next round of effort on the dispute, rather than rediscovering which spreadsheet holds the delivery record.
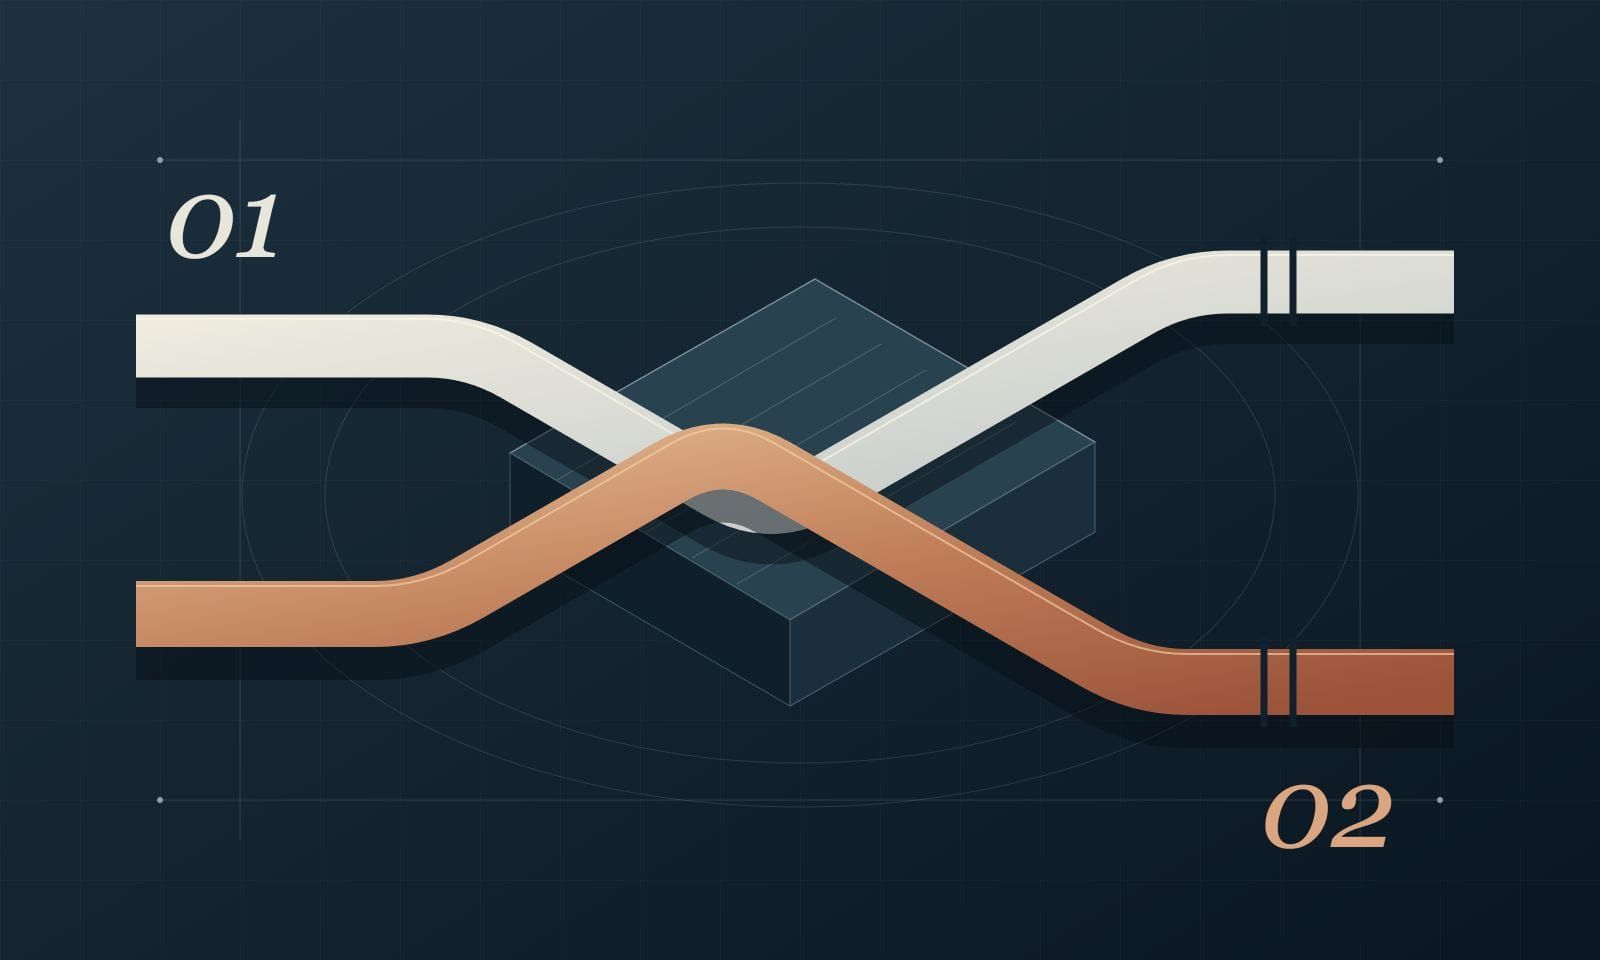
A shared foundation.
Two different decisions.
Keep these rules
specific to the work
What fails the match?
Who can place a hold?
What needs investigation?
Which agreement applies?
What remedy is permitted?
Who can commit to it?
- Source connections and document versions
- Consistent supplier and order identities
- Record-level access boundaries
- Evidence links and scoped corrections
- Checks for changes that break prior behavior
- A record of who approved what
In Stop Waiting for the Next Model, I argued for picking a real piece of work and building the first useful version. The second workflow tests whether that version left anything dependable behind.
Change the model later if a better one helps. The connection to the receiving system, the meaning of an accepted delivery, and the record of a corrected invoice match ought to remain useful.
Keep the decision specific
There is a temptation at this point to build one general agent for supplier operations. It has the records, after all. Give it a broad instruction and let it handle the rest.
The trouble is that access to evidence and authority to act are separate things.
An accounts-payable reviewer may be allowed to flag an invoice and hold it for investigation. A buyer may be allowed to negotiate a credit. Neither permission automatically includes changing an order, accepting revised terms, or sending a supplier a commitment on the company's behalf.
Those boundaries have to be carried into the second workflow deliberately. A connection that can read an invoice does not confer permission to send it outside the company. Approval to use an internal receiving note in a comparison does not make that note suitable for a supplier-facing message.
The domain work stays specific as well. A discrepancy threshold that helps prioritize invoice review says little about when a relationship warrants a phone call. A rule about rejected parts may depend on an inspection process the first workflow never touched.
I would want the procurement person beside the builder here. Show them the proposed message. Ask what would make them hesitate. Their objection might reveal an undocumented delivery agreement, a difference between sites, or a commitment the system is about to make without understanding it.
That is useful work. Trying to make the second workflow a copy of the first can erase exactly the expertise it needs.
A correction needs an address
Suppose the first workflow matched the invoice to the wrong delivery. The reviewer fixes it: the suffix on the order number identifies the receiving site. A match on the base number alone is unreliable.
The dispute workflow should benefit from that correction. The team should not have to discover the same error through an angry supplier email.
But how the correction travels matters. Saving “always match on the suffix” as a general instruction may break records from suppliers that use a different convention. Leaving the correction buried in a chat transcript makes it easy to miss. Silently changing a matching rule gives the next reviewer no way to understand the change.
A useful correction names the record, the rejected match, the accepted match, the reason, and where the rule applies. If the team believes it should become a general rule, someone needs to make and test that decision.
The corrected record travels.
Permission does not.
- Invoice review · human correctionReject the match to the wrong site.
The reviewer links the right delivery and records why: the order suffix identifies the receiving site in this order series.
- Shared evidence · bounded updateKeep the correction with its scope.
Preserve the source, rejected link, accepted link, reason, and applicable order series. Do not turn one correction into a universal rule.
- Dispute preparation · new evidenceUse the corrected link. Refresh the draft.
If a pending draft relied on the old match, flag it for review. Show the reviewer what changed before they act.
- Separate approval · procurementNo supplier message is sent yet.
The buyer still reviews the facts, proposed remedy, and commitment. A better match grants no new authority.
Now the second workflow can use the corrected link and show its origin. It still needs its own approval before sending a message. The evidence has become more reliable; the agent's authority has not expanded.
This is one of the reasons I care about the second deployment. It exposes whether the system remembers the work in a form another task can actually use.
Count the work around the system
A first deployment can look successful while carrying a surprising amount of labor just outside the frame.
The builder repairs a failed document fetch before the morning review. An analyst maintains the supplier-name lookup by hand. The reviewer opens three extra tabs because the evidence links lead to a folder rather than the cited page. Everybody is helping the pilot succeed.
Some of that is reasonable while learning. It becomes a problem when the team describes it as reusable infrastructure and multiplies it across more workflows.
For the second deployment, I would keep a blunt record of what people still do. How often does someone repair a connection? Which fields require manual interpretation? How much work goes into checking a draft? Can an ordinary reviewer trace an answer without asking the builder to explain it?
Getting to a draft faster is only part of the calculation. A dispute letter that takes two minutes to generate and twenty minutes to verify may offer little benefit. A system that saves the buyer time by quietly creating a daily cleanup job for an analyst has moved the burden.
There is also a cost to sharing too much. Change the invoice parser for the dispute workflow and you can break the invoice review that already worked. A shared component needs examples from both workflows before the team treats a change as safe.
The second deployment has to carry those costs in its account.
Run both workflows through the awkward cases
An easy second example proves very little. Pick a neighboring workflow that shares enough of the first problem to reuse its foundations, but asks a meaningfully different question.
Then run both through the cases people dread: a revised purchase order, a partial delivery, a stale receiving count, two suppliers with nearly identical names. Try a user who can read the invoice but cannot see the inspection note. Correct a record while a draft is waiting for review.
If the evidence changes, does the draft become visibly stale? If a source cannot be read, does the system say what is missing? When the reviewer rejects a recommendation, can the next run use the reason without applying it everywhere?
Watch the first workflow while testing the second. Its good behavior is part of what you are trying to preserve.
You may discover that the workflows should remain separate, sharing little more than access to a few records. That can be the right design. Reuse is valuable where it removes repeated work without blurring responsibility. A common layer that makes every change harder is a liability, however elegant it looks on a diagram.
Pick the task next door
The next useful step is modest. Put the proposed second workflow beside the first and mark what should carry over. Make the builder and the domain expert agree on what still needs a new decision, a new permission, or a new check.
Run it with the person who will own the result. Write down the repairs and the verification work. Check that the first workflow still holds up.
Then you can answer the question that matters: did the first deployment make this one easier because the system learned something durable, or because the same people worked harder again?
I would want that answer before calling it a platform.